About
About Me
I’m a researcher at Tencent Hunyuan LLM.
I finished my Ph.D. in Australian National University in Canberra, Australia, supervised by Prof. Nick Barnes. Before that, I received my Bachelors from both Beijing Institute of Technology(mechanics) and Australian National University(mechatronics).
Chatable
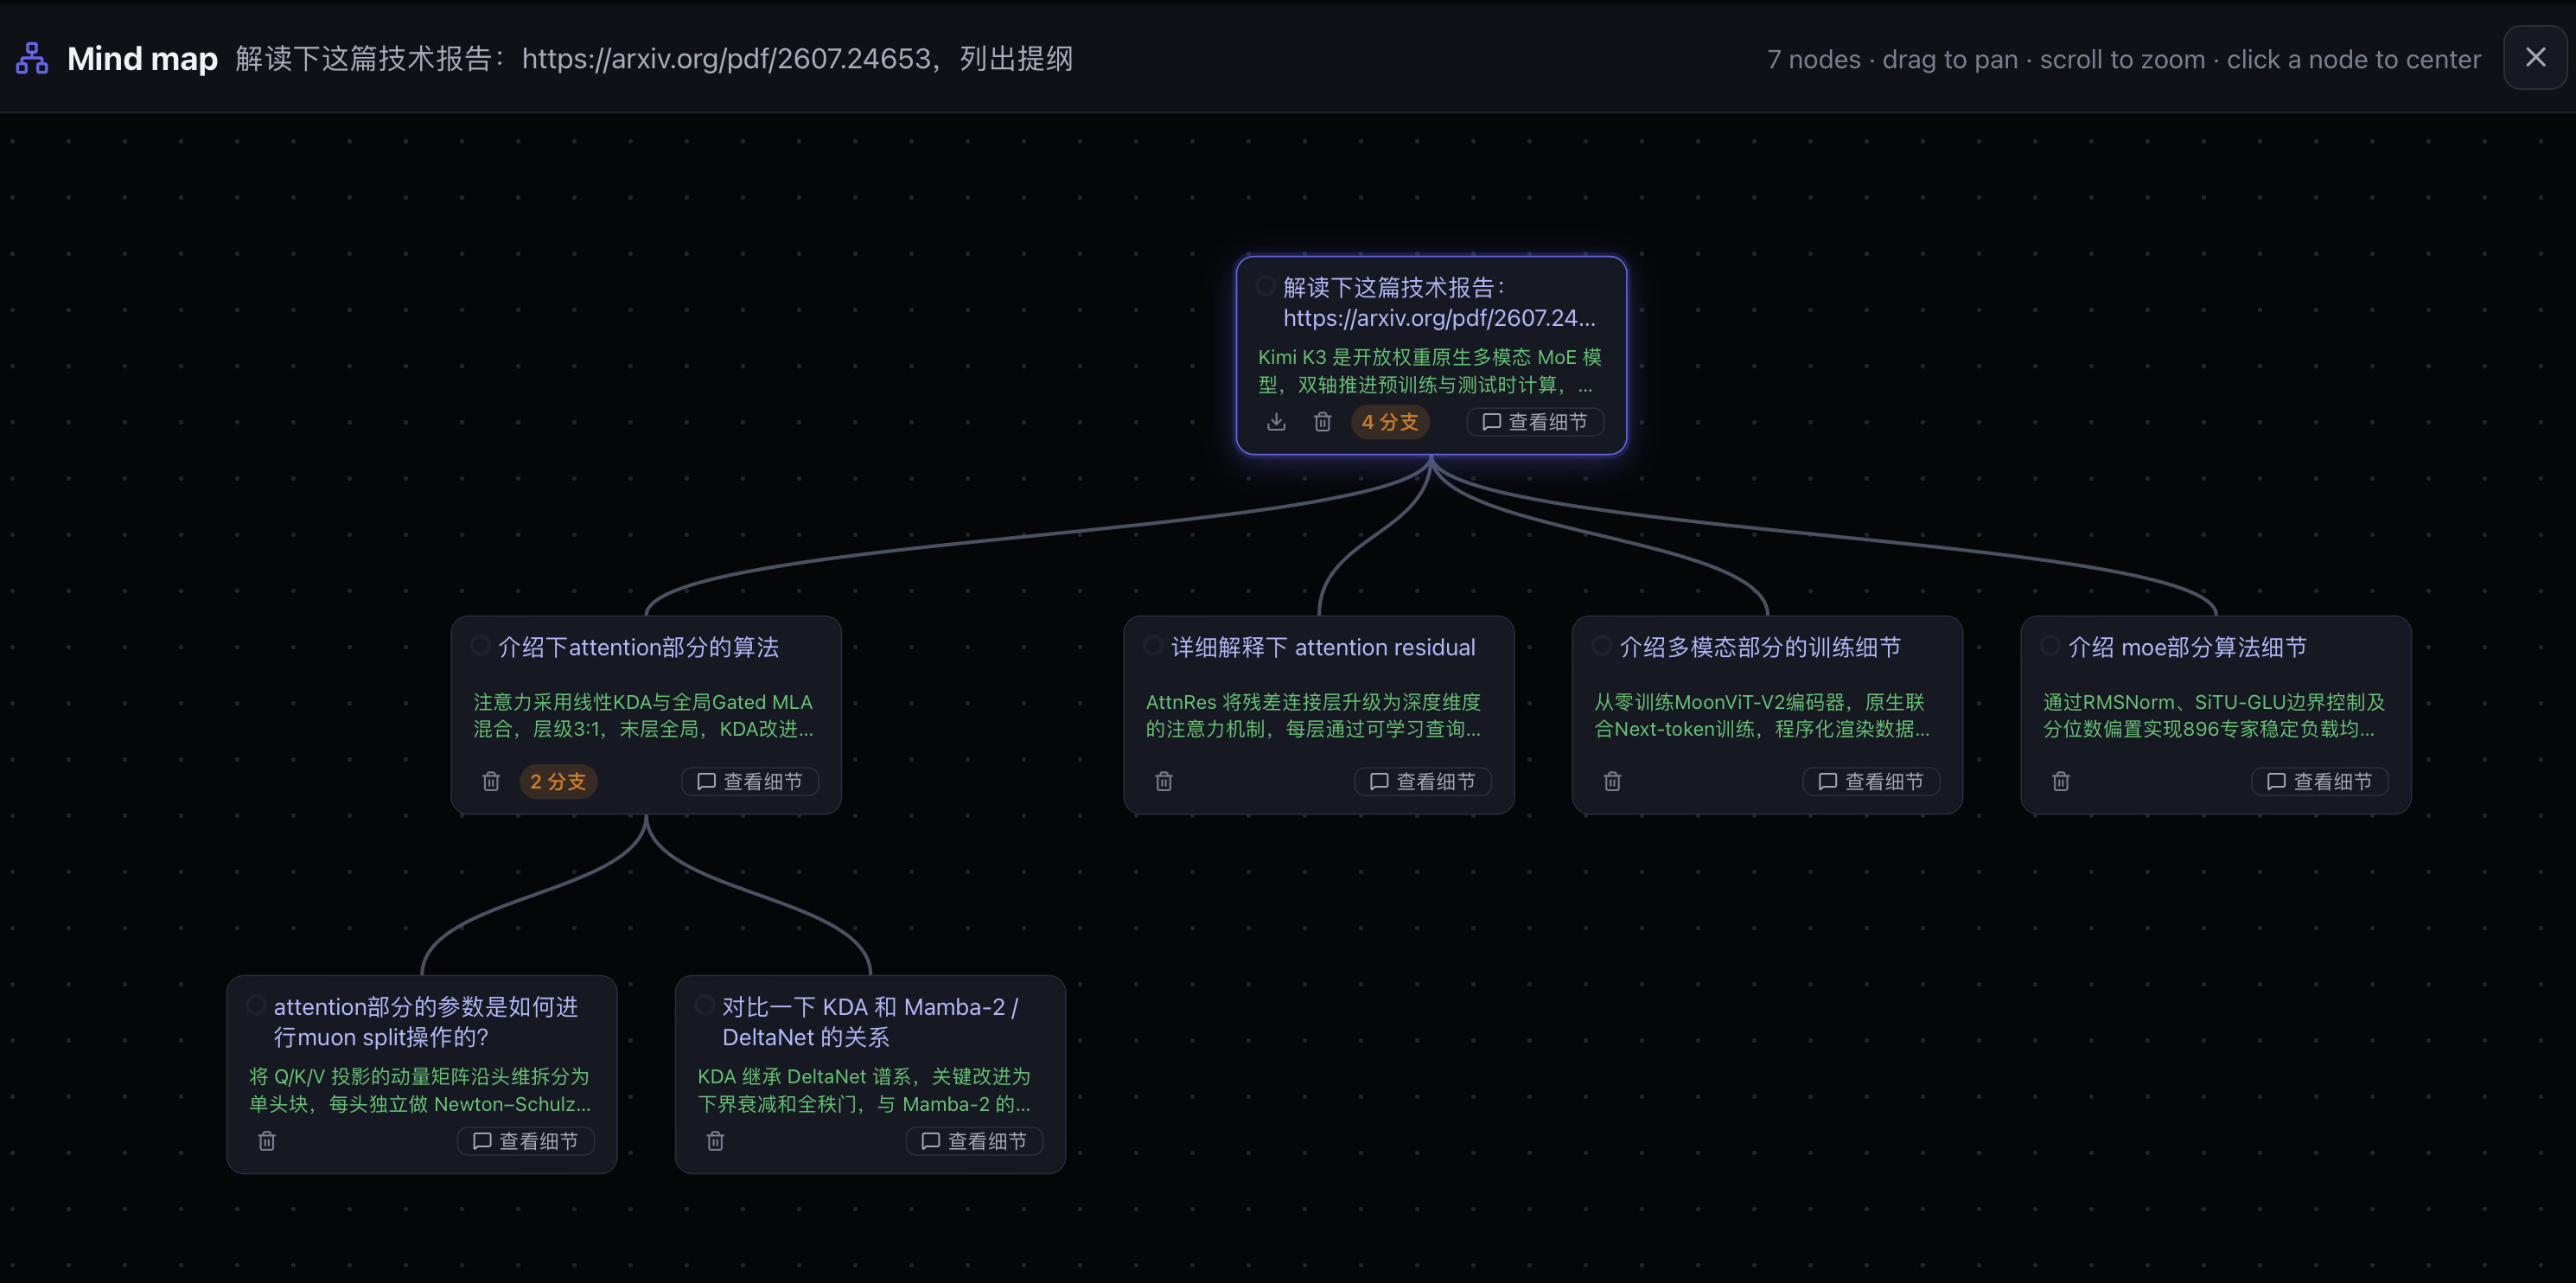
- chatable: I built a small tool to help with algorithm exploration and paper reading: chatable. A tree-structured research chat web UI. Conversations are organized as a tree — you can fork from any message node to ask a side question without polluting the main-line context, jump back to any earlier point, and view the whole session as an interactive mind map. It runs against your own LLM API key and stores everything on your local filesystem.
Selected Publications
My current research interests lie in large language models (LLMs), basically focusing on building more efficient, robust architectures. Prior to that, I have been working on image segmentation, multimodal and other interesting topics.
Model architectures
- Hybrid Gated Attention, preprint
- Hunyuan-TurboS: Advancing Large Language Models through Mamba-Transformer Synergy and Adaptive Chain-of-Thought
- Towards a Comprehensive Scaling Law of Mixture-of-Experts, EMNLP 2026
- MiniMax-01: Scaling Foundation Models with Lightning Attention
- Various Lengths, Constant Speed: Efficient Language Modeling with Lightning Attention, ICML 2024
- Lightning Attention-2: A Free Lunch for Handling Unlimited Sequence Lengths in Large Language Models, preprint
- HGRN2: Gated Linear RNNs with State Expansion, COLM 2024
- Vicinity Vision Transformer, TPAMI 2023
- TransNormerLLM: A Faster and Better Large Language Model with Improved TransNormer, preprint
- The Devil in Linear Transformer, EMNLP 2022
- Toeplitz Neural Network for Sequence Modeling, ICLR 2023
- Linearized Relative Positional Encoding, TMLR 2023
- cosFormer: Rethinking Softmax in Attention, ICLR 2022
image segmentation
- All-pairs Consistency Learning for Weakly Supervised Semantic Segmentation, ICCVW 2023
- An Alternative to WSSS? An Empirical Study of the Segment Anything Model (SAM) on Weakly-Supervised Semantic Segmentation Problems, preprint
- Inferring the Class Conditional Response Map for Weakly Supervised Semantic Segmentation, WACV 2022
- GETAM: Gradient-weighted Element-wise Transformer Attention Map for Weakly-supervised Semantic Segmentation, preprint
- 3D Guided Weakly Supervised Semantic Segmentation, ACCV 2020
multimodal & 3D generation
- Bi-directional Training for Composed Image Retrieval via Text Prompt Learning, WACV 2024
- Candidate Set Re-ranking for Composed Image Retrieval with Dual Multi-Modal Encoder, TMLR 2024
- Learning Audio-Visual Source Localization via False Negative Aware Contrastive Learning, CVPR 2023
- Audio-Visual Segmentation with Semantics, IJCV 2025
- Audio-Visual Segmentation, ECCV 2022
- BlockFusion: Expandable 3D Scene Generation using Latent Tri-plane Extrapolation, SIGGRAPH 2024
- LAM3D: Large Image-Point Clouds Alignment Model for 3D Reconstruction from Single Image, NeurIPS 2024
- NeuSDFusion: A Spatial-Aware Generative Model for 3D Shape Completion, Reconstruction, and Generation, ECCV 2024
- Frankenstein: Generating Semantic-Compositional 3D Scenes in One Tri-Plane, SIGGRAPH Asia 2024